Industry · Status at source date: Newsletter archive
GPT-5.6 API prices drop up to 80%, and Sol gains a Fast mode
OpenAI cut GPT-5.6 Luna token prices by 80% and Terra's by 20% in the API. Intelligence that was frontier-class a year ago now costs about six cents on the dollar per task at nearly nine times the speed, with gains spanning the model, inference stack, and agentic harness.
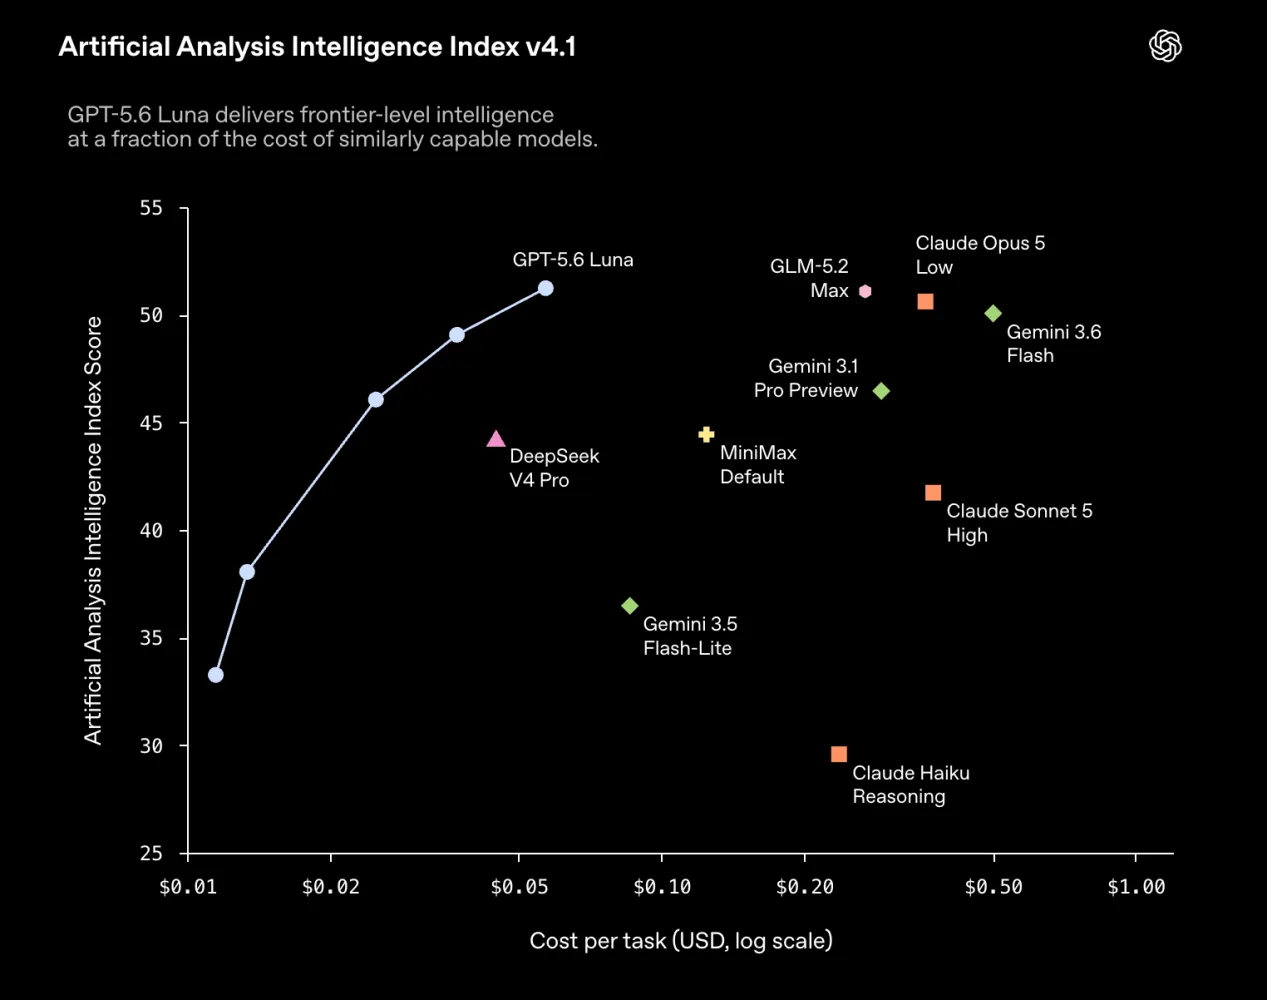
What changed
A Fast mode also arrives for GPT-5.6 Sol, offering up to 2.5 times Standard speed at twice the Standard price with no change in intelligence.
Why it matters for advertisers
For you, this means high-volume agentic work gets dramatically cheaper while latency-sensitive work gets a paid fast lane, so re-run the economics on automations you previously shelved.
Perspective from the original PMC newsletter.Sources & contributor credit
- Newsletter coverage · Paid Media Collective newsletter
Original newsletter text, contributor labels and media for this update.
- Source referenced in newsletterOpenAI
Linked from the original newsletter. The source publication date has not been independently confirmed.
Original creator unverified
The original creator has not yet been verified. Newsletter curation and publication do not establish original authorship.
Attribution evidence and limitations
Full attribution review pending.
A source link alone does not establish original authorship.
Original image and video creators have not yet been verified.
- Published on this site
This update reflects the dated source reporting. Availability may have changed. Further coverage of this same development will be added to this page.
Original newsletter text and archive evidence
GPT-5.6 API prices drop up to 80%, and Sol gains a Fast mode
OpenAI cut GPT-5.6 Luna token prices by 80% and Terra's by 20% in the API. Intelligence that was frontier-class a year ago now costs about six cents on the dollar per task at nearly nine times the speed, with gains spanning the model, inference stack, and agentic harness. A Fast mode also arrives for GPT-5.6 Sol, offering up to 2.5 times Standard speed at twice the Standard price with no change in intelligence. For you, this means high-volume agentic work gets dramatically cheaper while latency-sensitive work gets a paid fast lane, so re-run the economics on automations you previously shelved.
Source captured . No explicit first-contributor label was provided for this update.